Triangulating Incrementality Tests, MMM and Platform Attribution
No single measurement method tells you what your ads truly drive. Combining incrementality testing, marketing mix modeling and platform attribution gets you to a number you…
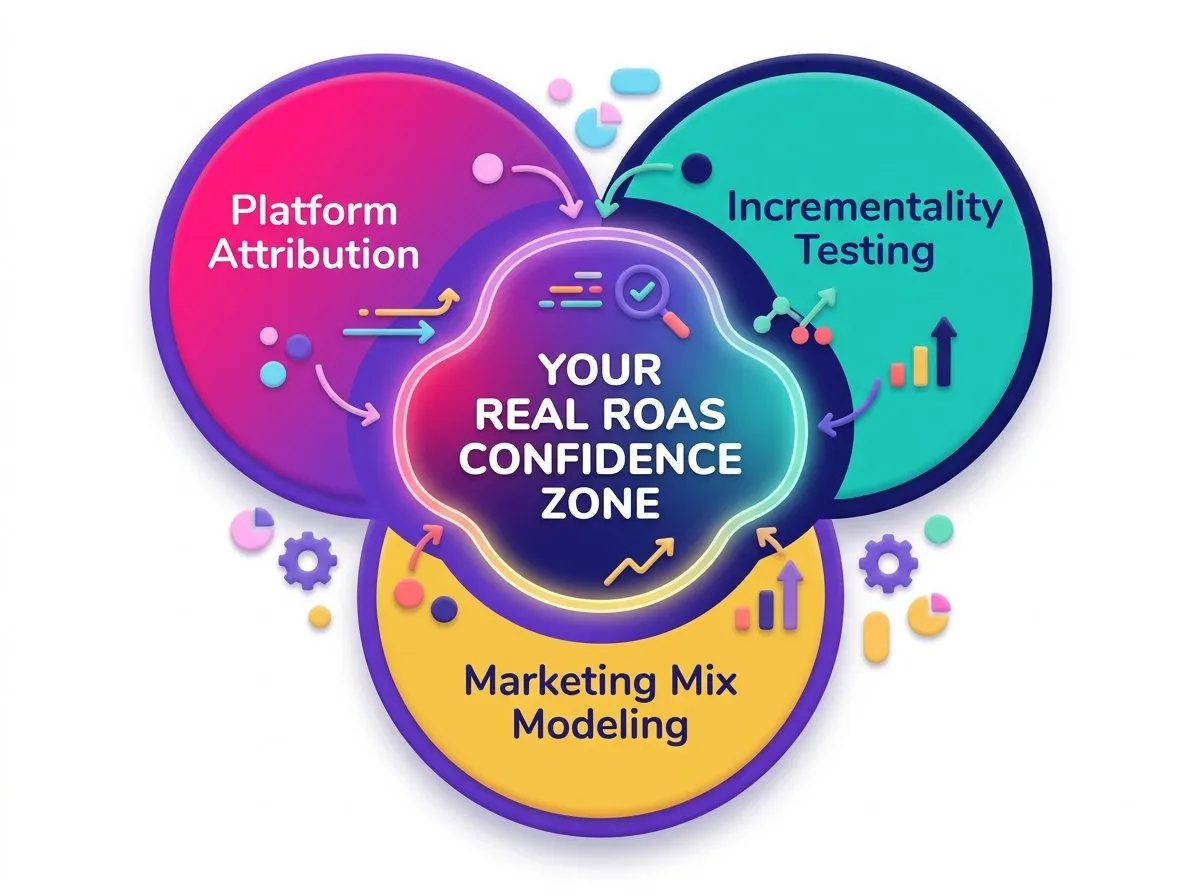
No single measurement method gives you an accurate number on its own. Platform attribution over-reports, incrementality testing answers a narrow question slowly, and marketing mix modeling gets noisy when spend history is thin. Because each method carries a different and fairly predictable bias, cross-referencing all three (triangulated measurement) has become the standard way to land on a figure you can actually act on.
If you have ever added up the conversions your ad platforms claim and found they exceed the orders in Shopify, this article is for you. I will walk through why platform attribution is structurally biased, what incrementality testing really measures, where marketing mix modeling fits, and how to combine the three into a weekly rhythm a lean team can maintain. The output is not a perfect number. It is a number you can defend in a budget meeting.
Why platform attribution alone keeps lying to you
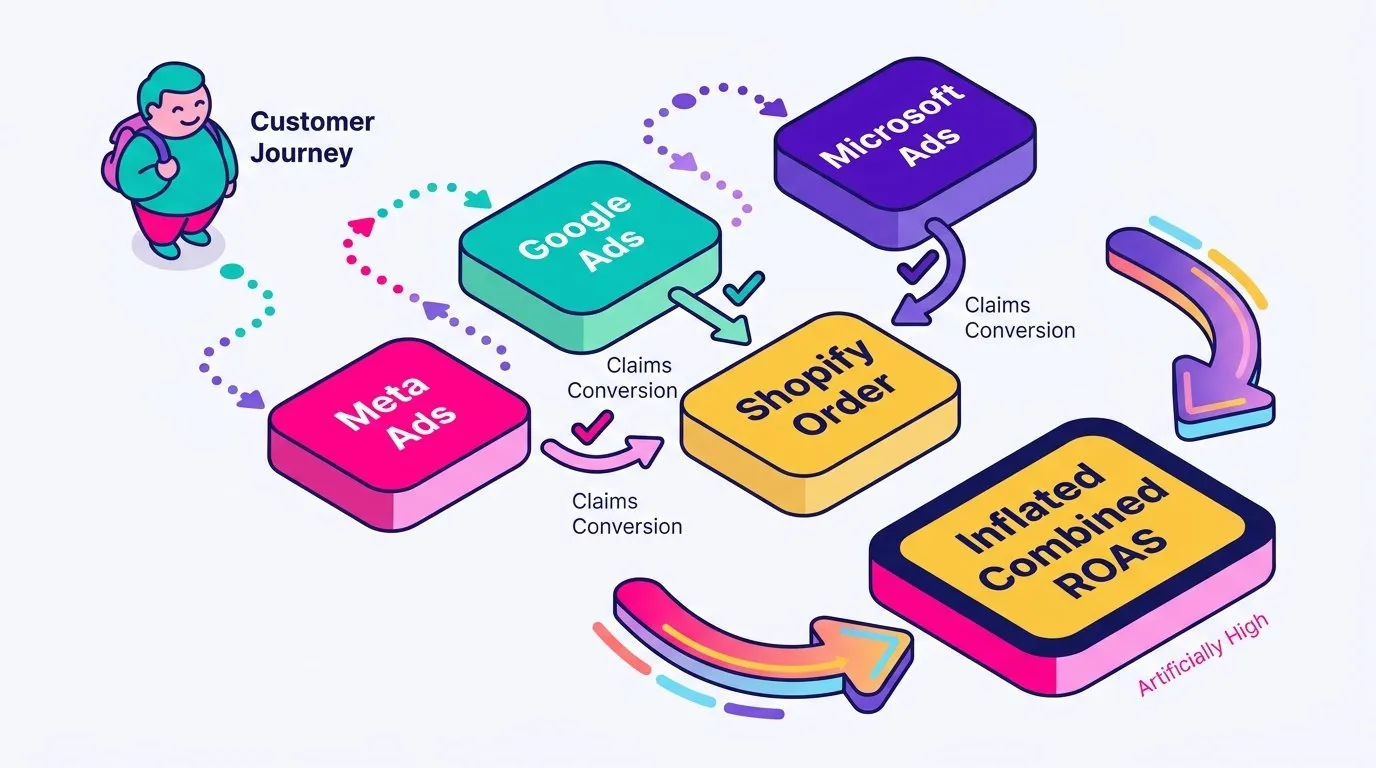
The scene I see most often when I open a new account: Google Ads reports 1,200 conversions, Meta reports 900, Microsoft Ads adds another 150, and Shopify shows 1,600 orders for the same period. Nobody is cheating. Each platform is counting the conversions it believes it influenced, using its own window and its own rules, and nobody is subtracting the overlap. The result is a combined ROAS that cannot be true because the revenue it implies does not exist in the bank account.
Last-click, view-through, and the self-reported ROAS problem
The mechanical reason is simple: every platform grades its own homework. Meta counts a conversion if the user saw or clicked an ad within its attribution window, which includes view-through. Google counts a conversion if it recorded a click in its own window. So a customer who scrolls past a Meta ad for a serum on Tuesday, searches the brand name on Google on Thursday, clicks the branded paid search ad and buys, gets counted once by Meta (view-through) and once by Google (last click). Both platforms are being internally consistent. Together they have sold you two sales where there was one.
Branded search is where this gets most expensive for Beauty and Fashion brands, because paid social and influencer activity create the demand and branded search harvests it. Platform attribution hands the credit to the harvester, which makes the cheapest channel look like the best investment and quietly starves the channel that created the demand in the first place. If you want the longer version of how attribution models distribute credit, I covered the model-by-model mechanics in our guide to ecommerce attribution.
iOS 14+, consent mode, and why pixels miss more conversions every year
On top of the over-counting there is under-measurement, and the two do not cancel out. Since Apple’s App Tracking Transparency framework rollout, a large share of iOS users never grant tracking permission, and in the EU, consent banners governed by frameworks like Google’s consent mode mean a meaningful slice of your traffic is never pixel-tracked at all. Add ad blockers, Safari’s cookie lifetime limits and privacy-focused browsers, and the pixel sees a shrinking sample of reality every year. This is not a bug that gets patched. It is the direction of travel.
Server-side tagging through Stape, a well-built GTM container and a properly configured consent management platform like Pandectes recover part of that signal. I implement this setup for a living, and it does improve data quality. It does not bring back the tracking environment that existed before privacy restrictions took hold. Even with perfect first-party data collection, a pixel can only tell you who clicked and who bought. It can never tell you what would have happened if the ad had not run. That question needs a different instrument, and that is the point where a serious first-party data strategy stops being enough on its own.
What incrementality testing actually measures
Incrementality testing answers the question platform data structurally cannot: how many of those sales would have happened anyway. It does this the way any serious experiment does, by creating a group that does not receive the treatment and comparing outcomes.
Holdout tests, geo-lift tests, and PSA/ghost ads explained simply
There are three practical flavors. A holdout test withholds ads from a randomly selected slice of your audience (say 10%) and compares their purchase rate against the exposed group. A geo-lift test turns spend off (or substantially down) in a set of geographic regions while keeping it running in comparable control regions, then measures the revenue gap. PSA or ghost ads serve the control group a neutral public service ad, or register that an ad would have been served without actually serving it, so you compare two groups that were equally targetable rather than comparing targeted people against everyone else.
Geo testing is usually the most practical option for a Shopify brand, because you do not need platform-level holdout features to run it and it captures cross-channel spillover. It also has real failure modes around market comparability, which is why I wrote a separate piece on how to design a geo-lift test properly.
What a “true” causal effect looks like versus a platform-reported one
Suppose your test region loses $40,000 in ad spend for three weeks and revenue drops by $112,000 compared to the control regions. That gap, roughly 2.8x, is the incremental return. Meanwhile the platform was reporting 4.2x on that same spend, because it was counting loyal repeat customers who were going to reorder their moisturizer regardless, plus people who clicked a retargeting ad on their way to a purchase they had already decided on. Neither number is a lie. They measure different things. The 2.8x is the one that changes if you cut the budget.
The honest caveat: incrementality tests are expensive and slow. You need enough spend and enough orders in both groups to detect a difference that is not just noise, which in practice means at least two to four weeks of running time and a market where you can afford to deliberately suppress demand. They also answer a narrow question, this channel, this period, this creative mix, rather than giving you a number that updates every Monday. You run them to calibrate, not to monitor.
Where marketing mix modeling fits in
MMM is the method furthest from my usual toolkit, which is exactly why I trust it as an outside check. It does not touch a pixel, a cookie or a click.
MMM for ecommerce: regression on spend versus revenue over time, not clicks
A marketing mix model takes your weekly spend by channel, puts it alongside everything else that moves revenue (seasonality, promotions, price changes, email sends, product launches, even weather in some categories) and fits a statistical model that estimates how much each input contributes to total revenue. Because it works on aggregate time-series data, consent rates and iOS restrictions are irrelevant to it. For a brand running heavy influencer and organic social activity that leaves no clean click trail, marketing mix modeling for ecommerce is often the only method that sees those channels at all.
Triangulated measurement means cross-referencing incrementality tests, marketing mix modeling and platform-reported attribution, then trusting the zone where they overlap more than any single source. You are not looking for one method to win. You are looking for the range they agree on.
Why MMM is directionally strong but noisy at small sample sizes
The catch is that regression needs variation to learn from. If your Meta spend has sat at roughly $30,000 a month for eighteen months, the model has almost no evidence about what happens at $15,000 or $60,000, and it will still happily give you a coefficient. If you launched TikTok eight weeks ago, MMM has nothing useful to say about it yet. In my experience, you want at least one to two years of weekly history before taking channel-level output seriously, with refreshes monthly or quarterly rather than weekly.
There is also an access problem. Enterprise MMM vendors price their work for brands spending far more per month than a $1M to $20M Shopify business spends in a quarter. That gap is real, and it is why a lightweight, spreadsheet-level model matters for this segment. I will come back to that. If measurement fundamentals are still settling for your team, our guide to web analytics covers the groundwork these three methods sit on top of.
The triangulation framework: how the three methods check each other
My guiding principle here is that no method is true, only useful. Each of the three is wrong in a direction you can predict, and that predictability is what makes the combination work.
A simple matrix: method, speed, cost, bias direction, best use case
Method
Speed
Cost
Known bias
Best used for
Platform attribution
Daily
Near zero
Over-attributes, double counts across platforms
Week-to-week trend direction, creative and campaign comparisons
Read it as a set of complementary instruments rather than a ranking. Platform data is fast and biased high. Lift tests are slow and closest to causal. MMM is medium on both axes and sees channels the other two miss. You use the fast one to notice changes, the slow one to correct the fast one, and the middle one to sanity-check the whole allocation.
What to do when all three disagree (and they will)
The decision rule I use is deliberately blunt. When all three land in a similar range, act with confidence and move budget. When two agree and one is an outlier, lean toward the pair but check the outlier for a cause before dismissing it. When all three diverge wildly, stop and investigate rather than picking a favorite, because wide divergence almost always points at something specific: a tracking break that started mid-period, a promotion the MMM did not know about, a geo test with mismatched control markets, or a seasonal spike that happened to land inside your test window.
That last scenario is the one worth sitting with. A three-way disagreement is information. It tells you your measurement setup has a problem, and that is more valuable than a confident wrong number.
Building a triangulation cadence for a $1M to $20M Shopify brand
None of this works if it requires a data science team you do not have. What makes it sustainable is assigning each method the frequency it deserves.
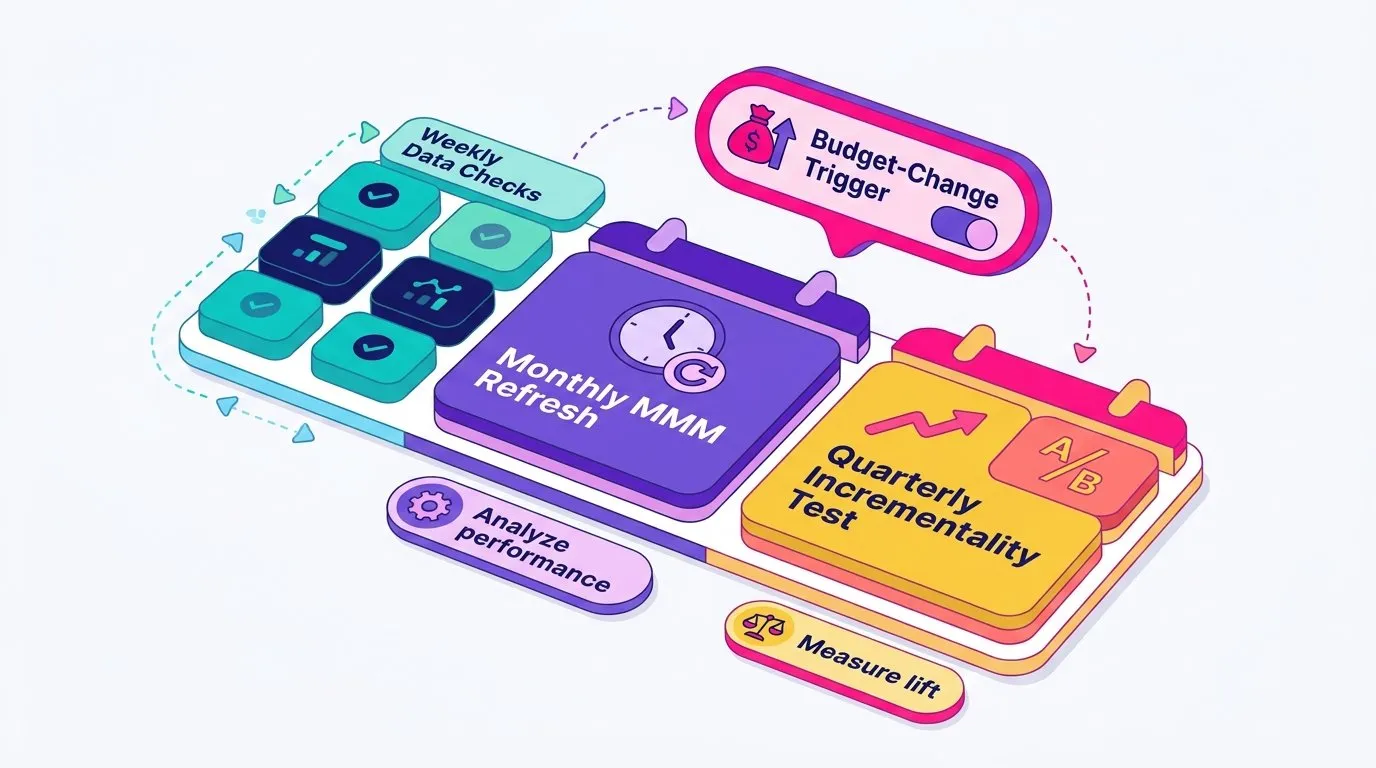
Weekly, you look at platform data and GA4 for direction only: is spend efficiency trending up or down, which creatives are moving, where did CPMs jump. You do not make structural budget decisions on these numbers, you use them to spot changes worth examining. Quarterly, or whenever you are about to make a significant budget shift, you run a lift test on your largest channel. In between, you keep a lightweight MMM refreshed monthly so allocation questions have a cross-channel answer that does not depend on pixels.
A practical trigger: before you increase a channel’s budget by more than about 30%, run a lift test on it first. Scaling a channel whose incremental return you have never measured is the most common way I see brands turn a healthy MER into an unhealthy one, which is why our guide on scaling ROAS-positive digital ads without killing performance pairs directly with this trigger.
Tools that make this realistic without a data science team
For the behavioral and platform layer, GA4 plus a clean GTM setup covers what happened on site, and Microsoft Clarity shows you how people actually behaved on the pages your ads send them to, which matters when a lift test comes back weak and you need to know whether the problem is the ad or the landing page. For MMM at this revenue stage, a weekly spend-and-revenue regression in Google Sheets is genuinely enough. You are looking for channel-level direction and diminishing returns, not a nine-figure media plan.
The part that kills most triangulation efforts is manual data collection, and that part is solvable. I use Make to pull spend and conversion data from Google Ads, Meta, Microsoft Ads and Shopify into a single sheet on a schedule, so the model refreshes itself and nobody spends Monday morning exporting CSVs. Supermetrics does the same job if you prefer a more off-the-shelf route, and Looker Studio sits on top of either for the reporting layer. Set this up once and the ongoing cost of triangulation is close to an hour a week.
A worked example: reconciling three conflicting ROAS numbers
Here is the situation in concrete terms, using the kind of numbers I see on a mid-size paid social account.
Confidence-weighted ROAS as the output metric that survives the disagreement
Platform attribution reports 4.2x on Meta. A geo-lift test run over three weeks comes back at 2.8x. The MMM says 3.1x. Picking one of these is a political decision, not an analytical one, and whichever number you pick someone on the team will have a reason to distrust it. Instead, weight each input by how much you trust it for this specific question, and be explicit about the weights.
Input
Reported ROAS
Confidence weight
Reasoning
Contribution
Geo-lift test
2.8x
50%
Causal, recent, ran on this exact channel
1.40
Marketing mix modeling
3.1x
35%
Cross-channel view, 18 months of history, no pixel dependency
1.09
Platform attribution
4.2x
15%
Fast and granular, but double counts and over-credits retargeting
0.63
Weighted result
3.12x
100%
3.12
The weights are a judgment call, and they should be. If your lift test ran during a promotional period, drop its weight. If your MMM has only nine months of history, drop its weight and lean harder on the test. What matters is that the weighting is written down, agreed on by the team, and revisited when new evidence arrives, rather than silently living in whoever’s dashboard shouts loudest.
Then use the output for what it is good for: budget decisions. Compare that 3.12x against your break-even threshold (if you have not pinned yours down, our piece on break-even ROAS walks through the calculation) and against blended performance, which you can model quickly with our MER calculator. The number will move as the next test and the next MMM refresh come in. That is the system working, not the system failing. The point of building this into client reporting is that the team stops arguing about whose dashboard is right and starts arguing about where the next $10,000 goes, which is a far more productive argument.
Common mistakes when triangulating measurement
I have seen the same handful of execution errors undo otherwise solid setups.
Over-trusting MMM at low spend, running lift tests too short, ignoring seasonality
The first is treating MMM coefficients as gospel when the spend history behind them is thin or flat. A model fitted on six months of near-constant spend will still output a confident-looking number, and that number is mostly an artifact of the model structure. The second is ending a lift test the moment the gap looks interesting. Early results in a two-week test swing wildly, and stopping when the answer is pleasant is how you convince yourself of something false. Decide the test duration before you start and hold to it.
The third is comparing periods without accounting for seasonality or promotions. Run a geo test during your Black Friday and Cyber Monday push and you have measured the seasonal spike, not your ads. Fashion brands running seasonal drops have this problem acutely: a test window that overlaps a launch will show inflated lift that has nothing to do with media efficiency.
There is also the temptation toward false precision, and I have some sympathy for it because a decimal point feels like rigor. It is not. Your real incremental ROAS is a range, something like 2.7x to 3.4x, and the honest output of triangulation is that range plus a central estimate you are comfortable acting on. Anyone promising you a single true figure to two decimal places is selling you confidence rather than measurement. And yes, when three numbers are on the table, there is a natural gravitational pull toward the most flattering one. Writing the weights down in advance is the cheapest defense against that.
Final thoughts on finding a number you can trust
Triangulation is not about chasing a flawless number. It is about attaching the right amount of confidence to a decision, and that is an achievable standard for a two-person marketing team running a Shopify store and a spreadsheet. You do not need an enterprise measurement stack. You need one causal test a quarter, a simple model refreshed monthly, and the discipline to treat platform numbers as a trend indicator rather than a verdict.
I think about it the way I think about preparing an opening in chess. You do not win by predicting your opponent’s exact move, because you cannot. You win by preparing solid responses across the several lines they are likely to play, so whatever happens you have a reasonable continuation ready. Triangulation is the same logic applied to measurement: you are not betting everything on one method being right, you are building a position that holds up whichever method turns out to be closest.
The unglamorous part is the plumbing underneath, the GA4 configuration, the GTM container, the server-side setup, the Clarity recordings, the automated data pulls that keep the whole thing fed. That reconciliation work is what our web analytics practice is built around, for brands who would rather have it designed into their reporting than assembled from scratch every time a number looks wrong.
Want to stop guessing which dashboard to believe? Request a measurement audit and we will map your current tracking setup, show you where the numbers diverge and why, and build the reconciliation layer that turns three conflicting ROAS figures into one decision you can act on.